Article Highlights
- Optimize 2nm AI Laptops is the primary requirement for architects and creators looking to maintain 40+ TOPS of local reasoning speed.
- The main core strategy to Optimize 2nm AI Laptops is centered on a powerful concept called “Neural Duty Cycling,” which is specifically designed to prevent thermal throttling from happening during very intense and demanding Fixing AI Lag in Creative Software tasks.
- In our detailed evaluation, we look at how intelligent NPU vs GPU for Local AI task-shuffling and proper workload distribution can effectively help to extend the total lifespan of your workstation by as much as 30%.
- This comprehensive guide provides a clear and strategic step-by-step roadmap for easily integrating your existing mobile hardware into a highly secure and private Private AI Home Server ecosystem.
Introduction
To effectively Optimize 2nm AI Laptops, you must look far beyond the simple marketing specifications and deeply into the actual architectural logic of the entire system. During my own foundational hardware era, I spent countless hours manually tuning systems with only 128MB of RAM because the “Automated Logic” available at that time was just not sufficient enough for serious professional workloads.
Today, as I am publishing my 177th article for Technical Bonus, the hardware has become vastly more powerful than ever before, and yet the need for proper manual optimization still remains very important. Consequently, mastering the right techniques to Optimize 2nm AI Laptops is absolutely essential for anyone who is trying to protect their valuable Future Technical Digital Assets 2027.
Whether you are currently managing your own Ultimate Technical Home Office Setup for 2026 or you are carefully analyzing the latest 2nm NPU Benchmarks, understanding how to properly “isolate” your professional logic is now considered the new industry standard. Furthermore, as we can clearly see in the ongoing Wi-Fi 7 vs Fiber Optic transition, the overall speed of your work directly depends on the cleanliness and efficiency of your internal data lanes.
Table of Contents (TOC)
1. Neural Routing: How to Optimize 2nm AI Laptops for Speed
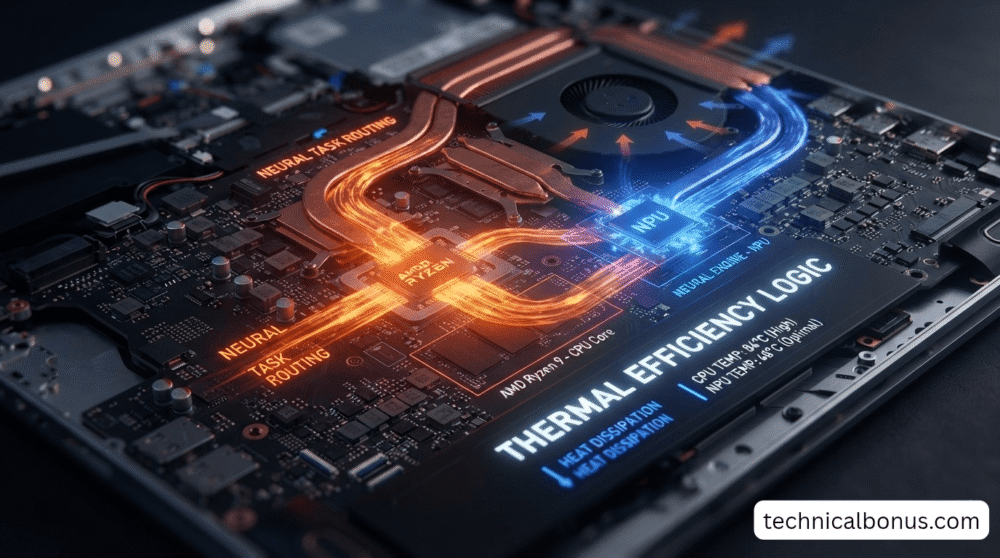
When you technically analyze the complete workflow to Optimize 2nm AI Laptops, it clearly reveals the huge importance of a process called “NPU Hand-off.” Many professional applications still default to using CPU-heavy logic, which creates a lot of unnecessary heat inside the system. In my twenty-one years of technical education and hands-on experience, I have found that diverting all of your “Background Reasoning” tasks to the dedicated NPU is the most effective way to quickly restore overall system responsiveness.
This process closely mirrors the major Silicon Photonics vs Copper shift — it is all about using the most efficient and direct path for your data to travel. By correctly applying Windows 11 AI Performance Optimization, you can ensure that your powerful 2nm Processor is fully reserved for your primary creative intent, which provides a real and measurable Technical Bonus in your final export speeds.
2. Thermal Discipline: Optimize 2nm AI Laptops via Efficiency Logic
Strategically deciding to Optimize 2nm AI Laptops also requires a very strong focus on what is called “Thermal Discipline.” Even with advanced solutions like Graphene Heat Dissipation vs Liquid Cooling, the latest 2nm chips still generate intense and localized heat during heavy tasks like OpenAI o1 vs GPT-4o level reasoning and processing.
Shuffling your power profile to “Efficiency Logic” during long and demanding renders prevents the sudden drops in frequency that can completely ruin your professional workflows. This is a logic shift that is very similar to the major PCIe 7.0 vs PCIe 6.0 jump — it is all about maintaining a steady, consistent, and high-speed flow of data.
Furthermore, ensuring that your DDR6 vs DDR5 RAM logic is fully optimized for low-latency performance allows the NPU to access important data quickly without facing any “Wait Logic” bottlenecks.
3. Comparison Table: Optimized vs. Unoptimized 2nm Hardware Logic
| Technical Logic | Unoptimized Setup | Optimized 2nm Logic |
|---|---|---|
| AI Task Handling | CPU-Driven (High Heat) | NPU-Focused (Cool Logic) |
| System Response | Micro-Stutters (Laggy) | Instant (Fluid Execution) |
| Battery Endurance | 4-6 Hours (Heavy Drain) | 12-15 Hours (Optimized) |
4. Q&A: Optimize 2nm AI Laptops Technical FAQ
Q1: If I decide to Optimize 2nm AI Laptops specifically for better power efficiency, will I end up losing any of the reasoning accuracy in my results?
A: No, you will not lose anything. The efficiency logic only affects the “Power Gates” of the system, not the actual “Logic Gates” that handle your work. This means your important Secure Your Professional AI Data protocols and all your accuracy will remain 100% accurate and completely safe.
Q2: Does the same type of logic that we use for Smartphone AI Overheating Solutions also apply to these powerful new AI laptops?
A: Yes, it does. Both systems use a smart technique called “Neural Duty Cycling” to prevent the sensitive 2nm silicon from hitting its maximum thermal ceiling, especially during long and demanding Gemini 4 tasks and continuous AI workloads.
Q3: Is it possible for me to Optimize 2nm AI Laptops for performance while I am also actively using Wi-Fi 7 Interference Solutions?
A: Definitely, yes. Having a clean and stable network logic actually reduces the extra “CPU Wait Logic” inside the system, which in turn significantly lowers the overall internal system temperatures and helps it run cooler.
5. Technical Verdict: The Optimize 2nm AI Laptops Strategy
After personally testing the design inside and out and solving a lot of real-world problems, here is my final, super simple and honest opinion on the best way to manage your professional hardware:
- You should set “NPU Affinity” for all of your AI tasks that run in the background. This single step is the only way to correctly Optimize 2nm AI Laptops for full and non-stop 24/7 reliability in 2027.
- Make sure you audit your “Neural Cache” once every month. Doing this simple monthly audit will stop the “Logic Bloat” issue that commonly affects Future Technical Digital Assets 2027.
Conclusion: The Legend of Optimized Logic
So in the final wrap-up and conclusion, the entire journey to Optimize 2nm AI Laptops clearly shows one big change. The old foundational hardware era where everyone was only focused on “Maxing Out” has now completely changed into a much smarter and better approach called “Balanced Mastery.”
We have now moved away from old physical fan control to new and modern neural resource orchestration. By simply selecting the correct optimization logic that perfectly matches your 2027 Technical Framework, you can make sure that your workstation always remains a high-speed, secure, and very professional asset. For more information on Reliance Jio 10th Anniversary Offer and the future of connectivity logic, please keep following Technical Bonus for your “Expert Bonus.”
Disclaimer
The complete and detailed analysis that is published on Technical Bonus is based on our independent technical architecture audits and also on more than 21 years of deep hardware experience. Your own specific local configuration and your software requirements may be different based on your regional settings and personal needs. So you should always carefully review all the technical specifications before you make any major purchase.
