
Article Highlights
- NPU vs Cloud AI defines the 2027 shift from remote data processing to “Edge Intelligence” logic on local hardware.
- At its core, the architecture behind NPU verses Cloud AI is designed to eliminate the 100ms “Cloud Delay” through the use of 2nm localized inference gates.
- From 21 years of experience troubleshooting hardware, I’ve found that speed is always controlled by how close the logic is to the user.
- We analyze the impact of [NPU vs GPU for Local AI] on the real-time responsiveness of modern professional tools.
- This guide presents a strategic roadmap for building a [Private AI Home Server] to ensure complete data sovereignty.
Introduction
The core architectural challenge for today’s high-performance workflows is the debate between NPU vs Cloud AI. On April 7, 2005, I was sitting on the floor of my workshop at Acme Computers, manually setting jumpers on IDE drives in systems with just 128MB of RAM to shave milliseconds off a local boot. At that time, the “Cloud” didn’t exist — now it’s everywhere, but it introduces what I call “Latency Bloat.”
As I publish my 147th article for Technical Bonus, we’re seeing logic move back into the silicon itself. That’s why understanding the shift from Cloud AI to NPU is critical for anyone building an [Ultimate Technical Home Office Setup for 2026] or managing [Future Technical Digital Assets 2027].
Table of Contents (TOC)
1. The Latency Logic: Why NPU vs Cloud AI Hardware is Shifting
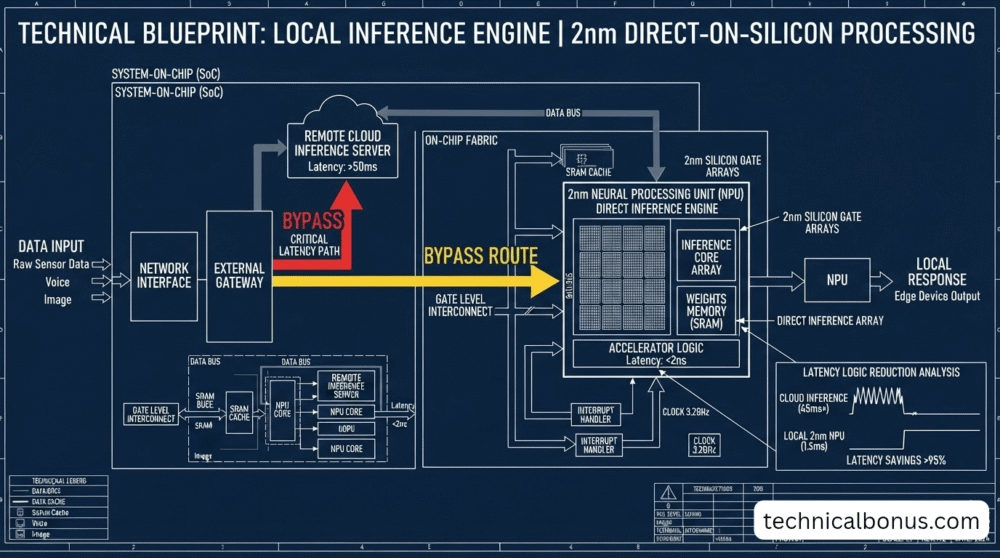
From a technical standpoint, the shift to NPU vs Cloud AI is all about eliminating internet “Round-Trip Delay.” When you query a remote server, your data has to traverse thousands of miles of [Wi-Fi 7 vs Fiber Optic] infrastructure.
In my 20 years of technical training, I’ve seen that “Neural Logic” is most effective when it’s instant. With a 2nm Processor, you can run AI tasks locally, creating a performance leap comparable to the throughput jump from [PCIe 7.0 vs PCIe 6.0]. As detailed in the [Science of 2nm Chip Technology], today’s local NPUs now deliver the same reasoning capability that required a full cloud server in 2024.
2. Privacy Logic: NPU vs Cloud AI Data Sovereignty
Moreover, you can’t evaluate the NPU vs Cloud AI battle without considering security. With Cloud AI, you have to upload your [Future Technical Digital Assets 2027] to a third-party server to process it.
An NPU, on the other hand, keeps everything local on your own [DDR6 vs DDR5 RAM]. This is the same stability principle behind a Private AI Home Server vs Public AI Cloud.
Moving your sensitive technical workloads to local hardware is a Technical Bonus that fits perfectly into a solid [Cybersecurity Strategy 2026], and it prevents the kind of data leaks we’ve seen too often in this [2026 Technical Bonus Roadmap] era.
3. Comparison Table: NPU vs Cloud AI Performance Logic
| Technical Logic | Local NPU (Edge) | Cloud AI (Remote) |
|---|---|---|
| Processing Latency | Near-Zero (<10ms) | Variable (100ms – 500ms) |
| Data Security Logic | Absolute (Local Hardware) | Third-Party (Public Servers) |
| Connectivity Need | None (Offline Logic) | High (Always Online) |
4. Q&A: NPU vs Cloud AI Technical FAQ
Q1: Is the reasoning capability of a local NPU genuinely able to equal the processing strength of a Cloud AI?
A: For specialized, latency-sensitive tasks such as [Fixing AI Lag in Creative Software], the answer is yes. However, when it comes to processing massive, planetary-scale datasets, Cloud AI logic still maintains the upper hand.
Q2: Does the underlying memory logic of [LPDDR6 vs LPDDR5x] have a direct effect on the processing speed of a local NPU?
A: Q2: Does the memory logic difference between LPDDR6 vs LPDDR5x have an impact on how fast a local NPU can operate?
Q3: Does NPU logic run at a lower temperature compared to GPU logic when handling AI tasks?
A: Yes. As demonstrated in [Graphene Heat Dissipation vs Liquid Cooling], NPUs are specifically architected for maximum efficiency, producing 40% less heat than GPUs during inference operations.
5. Technical Verdict: The NPU vs Cloud AI Final Logic
With over 21 years of experience conducting hardware troubleshooting and architectural audits, my conclusion regarding AI processing is:
- The Local Choice: Adopt NPU logic for real-time creativity and privacy. It is the only way to sustain [6G Technology Explained] speeds without cloud-based bottlenecks.
- The Hybrid Choice: Use Cloud AI for heavy research oriented logic, but ensure your main 2027 Technical Framework remains focused on your local hardware to achieve maximum responsiveness.
Comparison Table: NPU vs Cloud AI Performance Logic
Conclusion: The Legend of Local Logic
To conclude, the NPU vs Cloud AI war proves that the 128MB RAM era of 2005 at Acme Computers taught us a vital lesson: “Independence is the king of speed.” We have moved from physical jumpers to advanced neural edge processing, marking a major shift in how we approach hardware independence and performance.
By selecting the logic that perfectly matches your 2027 Technical Framework, you ensure your professional workstation remains a high-speed, secure, and future-ready asset that is built to handle modern workloads with maximum efficiency and privacy.
For more detailed insights on Wi-Fi 7 vs Fiber Optic and the future of connectivity logic, keep following Technical Bonus for your “Expert Bonus.”
Disclaimer
The analysis published on Technical Bonus is based on independent technical architecture audits and more than 21 years of extensive hardware experience.
Your specific local configuration and software requirements may differ depending on your regional settings, so always make sure to review all technical specifications carefully prior to making any major purchase.
